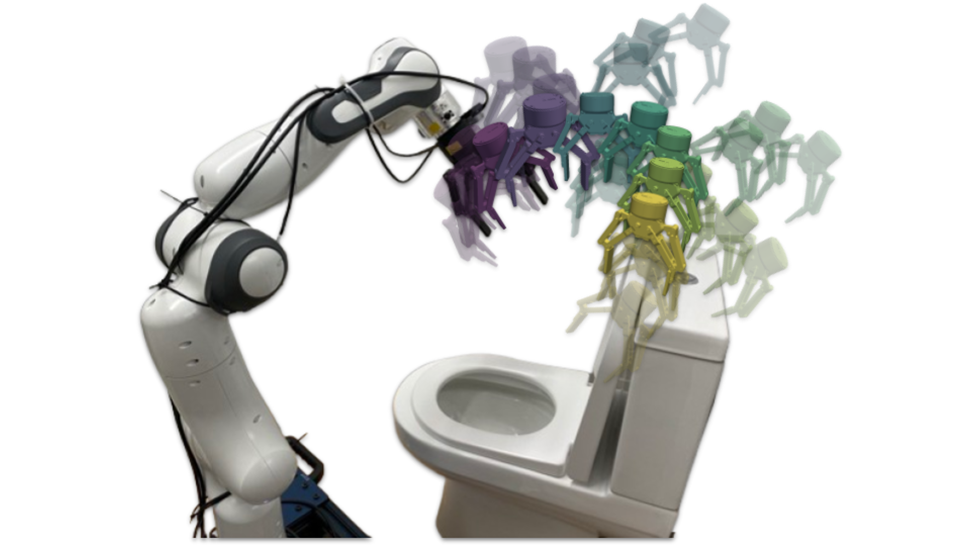
One of the biggest hurdles with teaching robots new skills is how to convert complex, high-dimensional data, like images from onboard RGB cameras, into actions that accomplish specific goals. Existing methods typically rely on 3D representations requiring accurate depth information, or using hierarchical predictions working with motion planners or separate policies.
Researchers at the Imperial College London and the Dyson Robot Learning Lab have unveiled a novel approach that could address this problem. The "Render and Diffuse" (R&D) method aims to bridge the gap between high-dimensional observations and low-level robotic actions, especially when data is scarce.