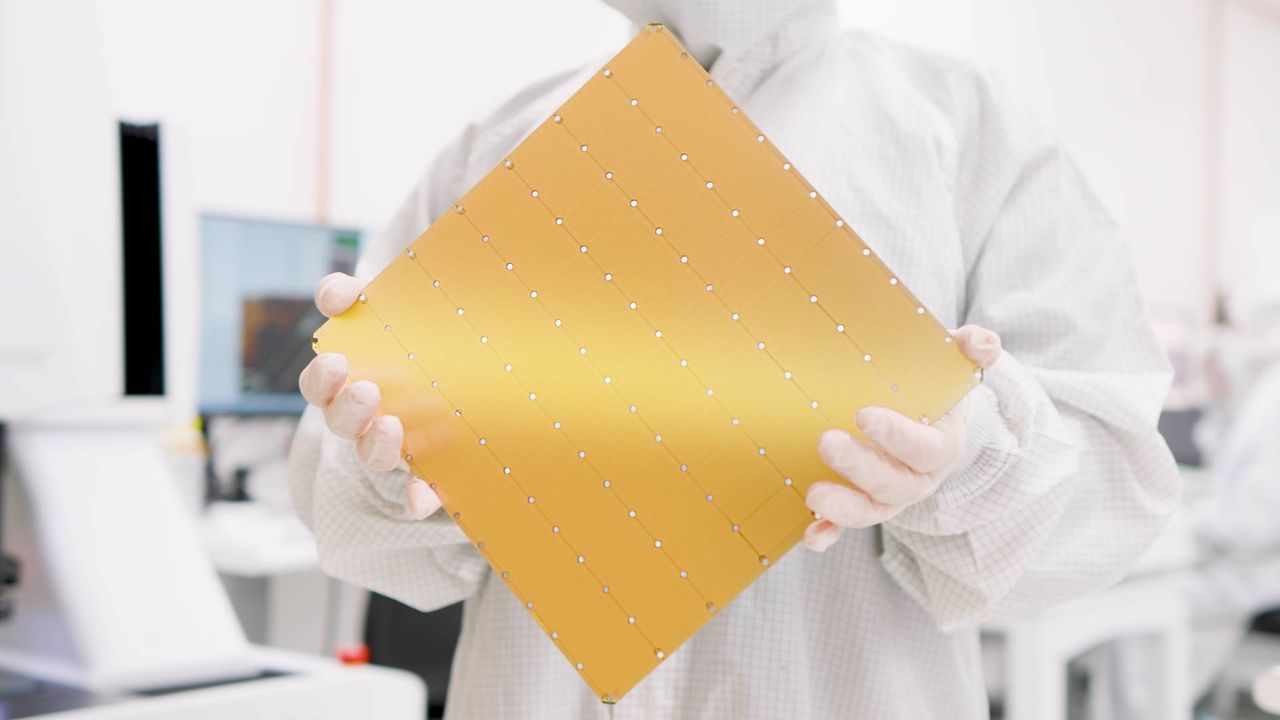
- AMD and Cerebras will split inference across two machines, with Helios racks handling prompt processing and the Wafer-Scale Engine generating tokens, available through Cerebras Cloud in H2 2026
- Nvidia is also doing something similar by licensing AI chip startup Groq's SRAM decode technology for $20 billion
- The move sees AMD and Cerebras claim 5x higher tokens per watt versus a standalone Cerebras WSE configuration
AMD and Cerebras Systems have announced a technical partnership which pairs the former's Helios rackscale system with the latter's Wafer-Scale Engine in what both companies call a disaggregated inference solution.