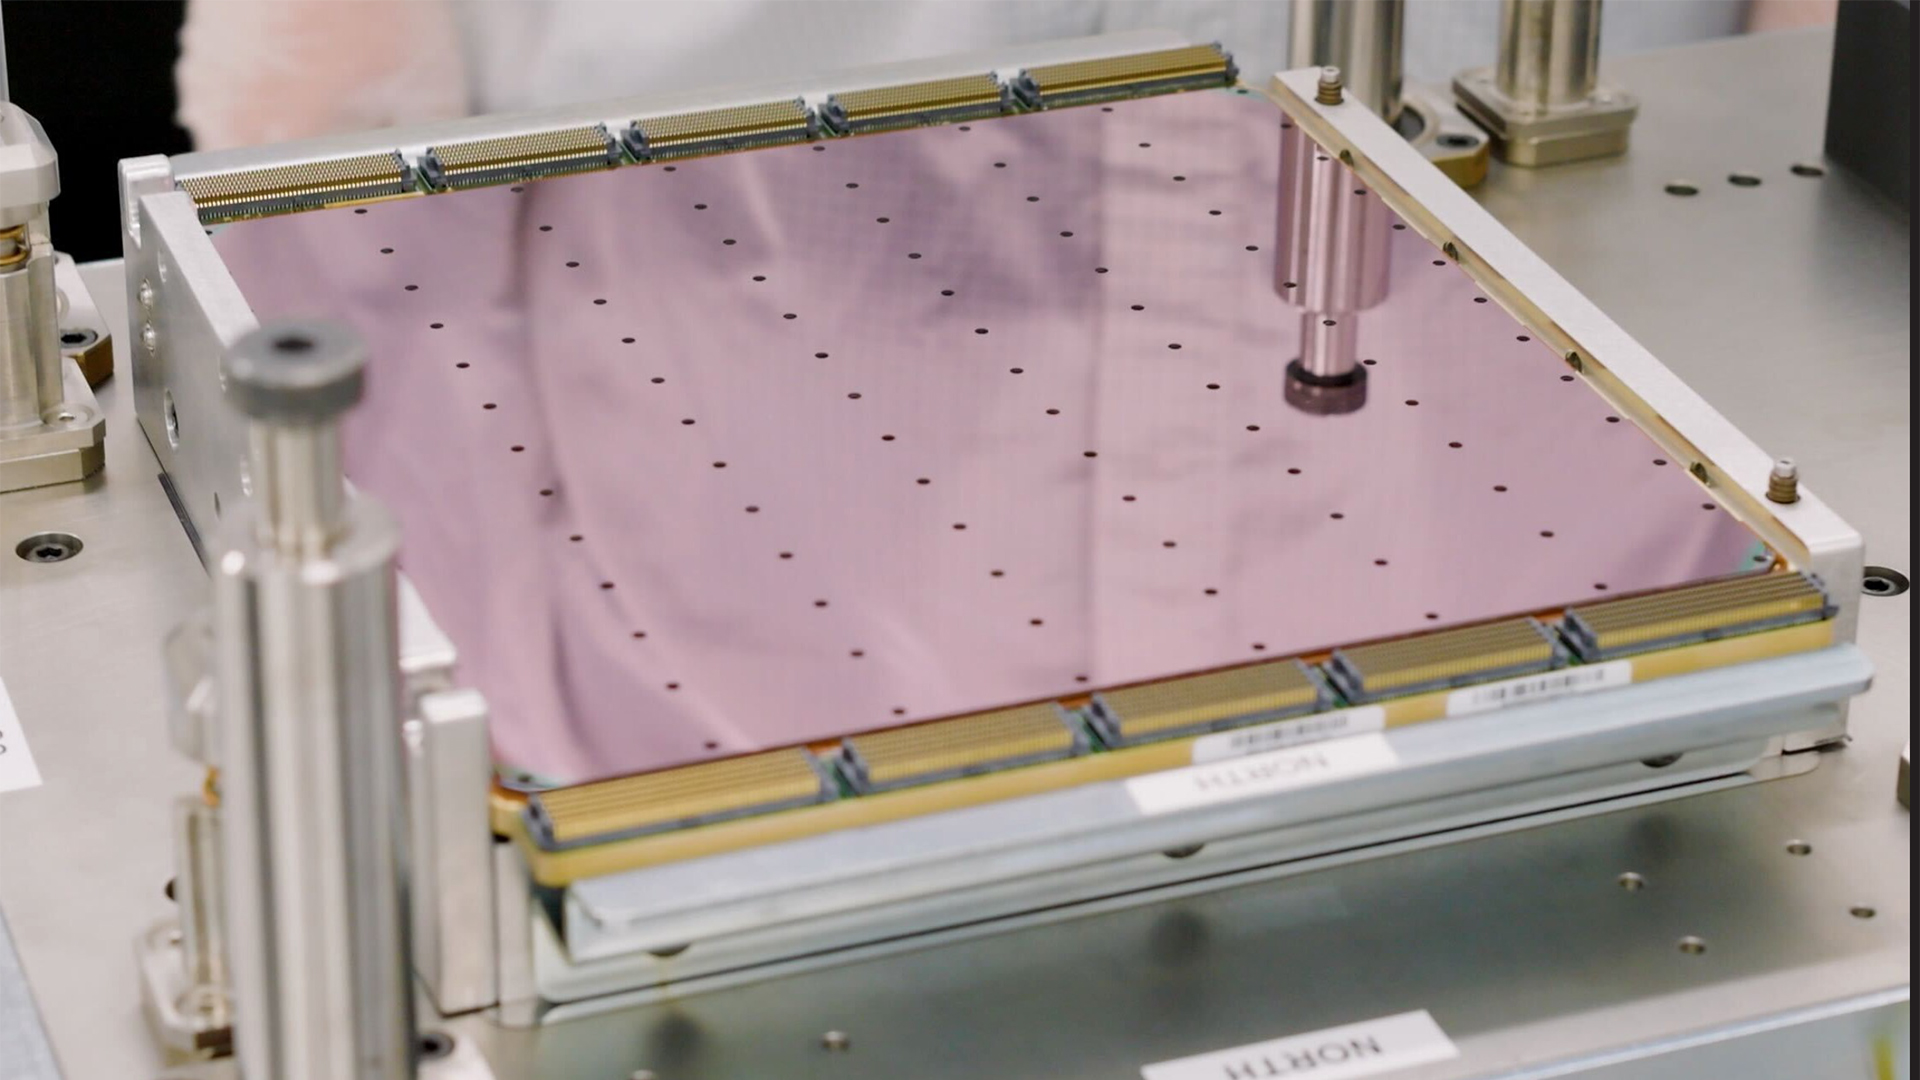
Cerebras got Meta’s Llama 3.1 405B large language model to run at 969 tokens per second, 75 times faster than Amazon Web Services' fastest AI service with GPUs could muster.
The LLM was run on Cerebras’s cloud AI service Cerebras Inference, which uses the chip company’s third-generation Wafer Scale Engines rather than GPUs from Nvidia or AMD. Cerebras has always claimed its Inference service is the fastest for generating tokens, the individual parts that make up a response from an LLM. When it was first launched in August, Cerebras Inference was claimed to be about 20 times faster than Nvidia GPUs running through cloud providers like Amazon Web Services in Llama 3.1 8B and Llama 3.1 70B.