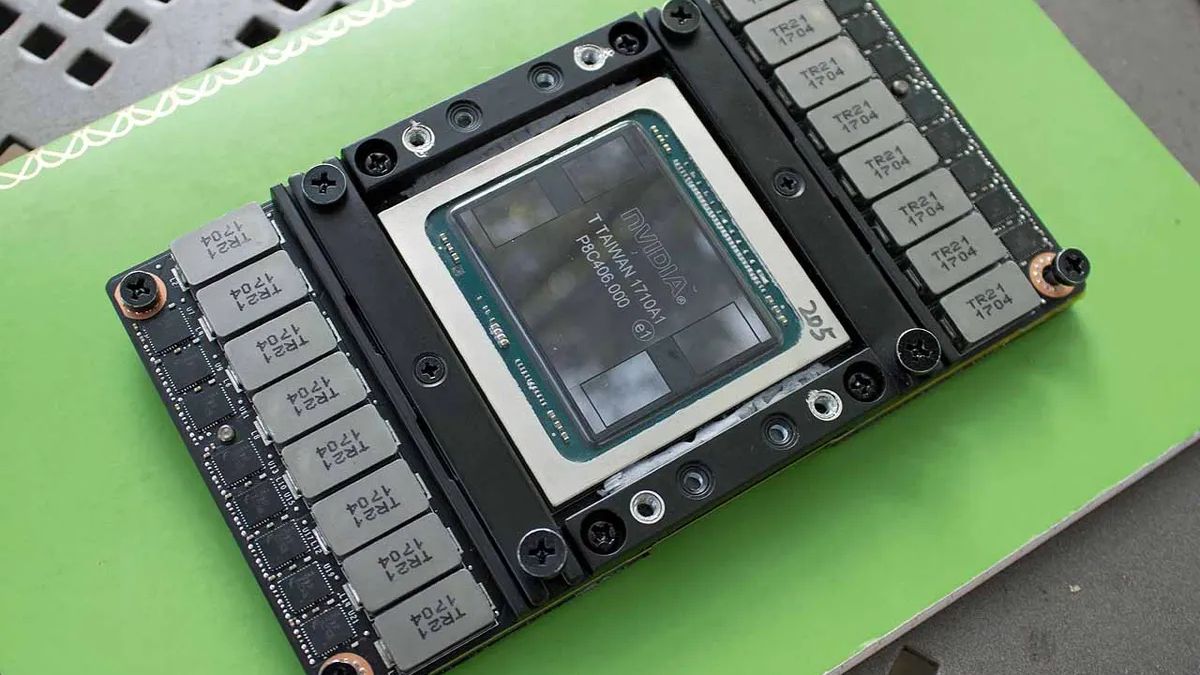
A computing enthusiast has repurposed a very noisy and largely obsolete enterprise GPU (with lots of VRAM) for local LLM inference purposes. They are now enjoying a system that has doubled its total VRAM quota to 32GB for just a $266 (£200) outlay. That’s a good result, especially in the midst of a RAMpocalypse.
Oscar Molnar explains that a cheap Tesla V100 SXM2 with 16GB HBM2 was sourced, as was an SXM2-to-PCIe adapter, and a PWM mod for the loud-as-a-lawnmower cooler, to complete this VRAM expansion for the hefty local LLMs project. Indeed, these GPUs do look cheap right now, as I can see them listed on eBay US for under $140 each, if you don’t mind buying from China.