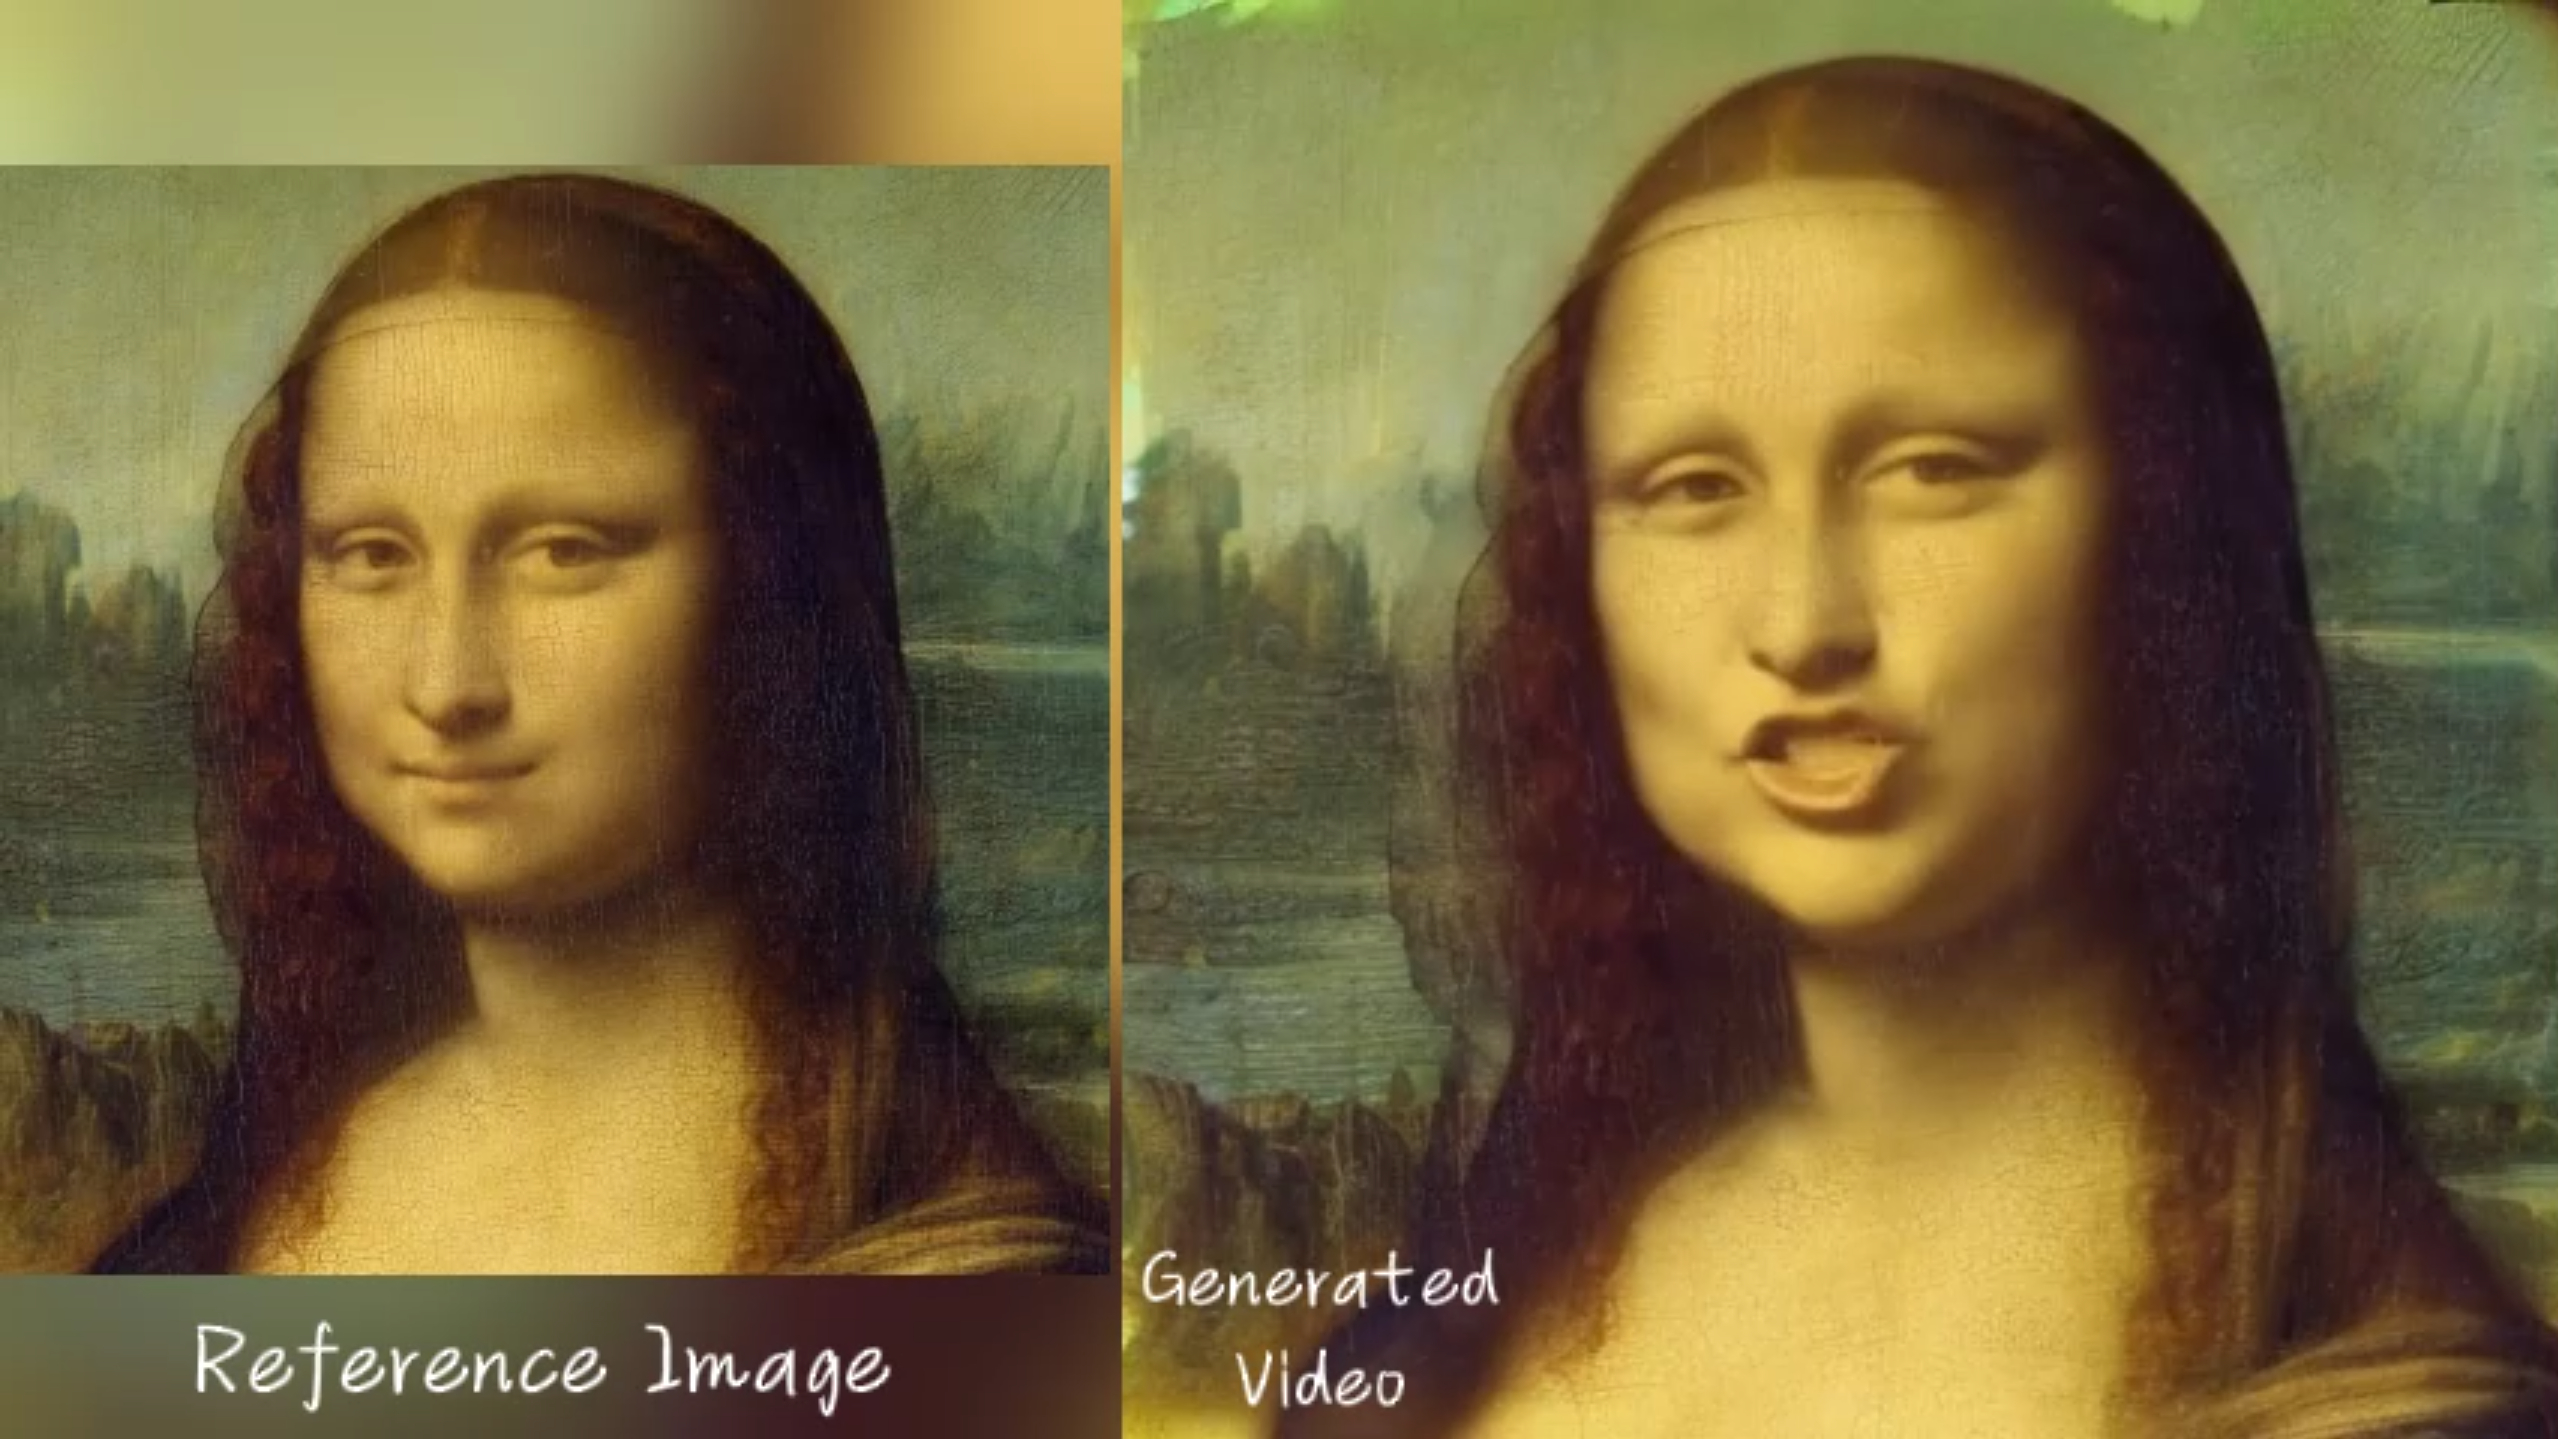
Remember that late-night talk show bit where an image of a political figure is shown with someone else's mouth superimposed on top, in order to make them say dubious things? It always looked a little ropey, but that was part of the effect. Well, this new AI tool also takes still images of human subjects and animates the mouth and head movements, but this time the effect is surprisingly, almost worryingly convincing.
The tool is called EMO: Emote Portrait Alive, and it's been developed by several researchers from the Institute for Intelligent Computing, part of the Alibaba Group. The tool takes a single reference image, extracts generated motion frames, and then combines them with vocal audio through a complex diffusion process in which the facial region is integrated with multi-frame noise samples and then de-noised while adding generated imagery to synch with the audio, eventually generating a video of the subject not only lip-synching, but also emoting various facial expressions and head poses.