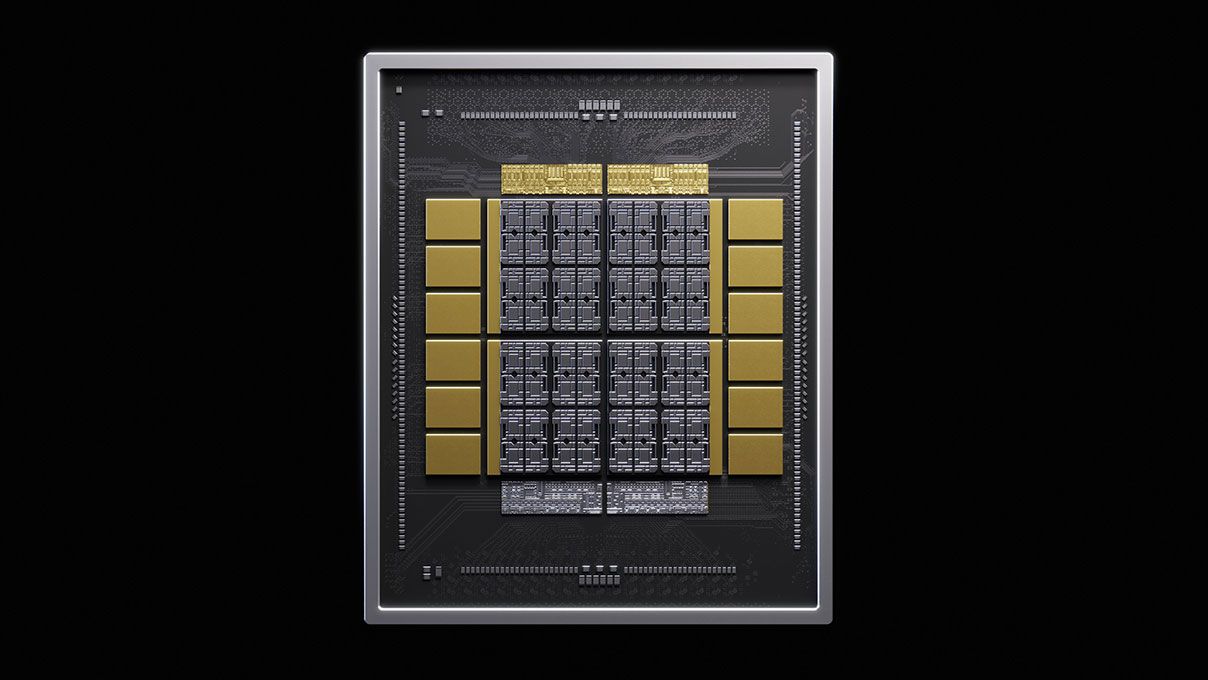
Nvidia's NVLink Fusion program gives the company's partners the building blocks necessary to connect custom chips with the NVLink scale-up domain used to join many separate processors into a single coherent system like the Vera Rubin NVL72 rack-scale accelerator. Today, Nvidia is adding a new building block to that toolkit: NVHBM, a custom implementation of the high-bandwidth memory that underpins practically every AI accelerator in use today.
Go deeper with TH Premium: Memory