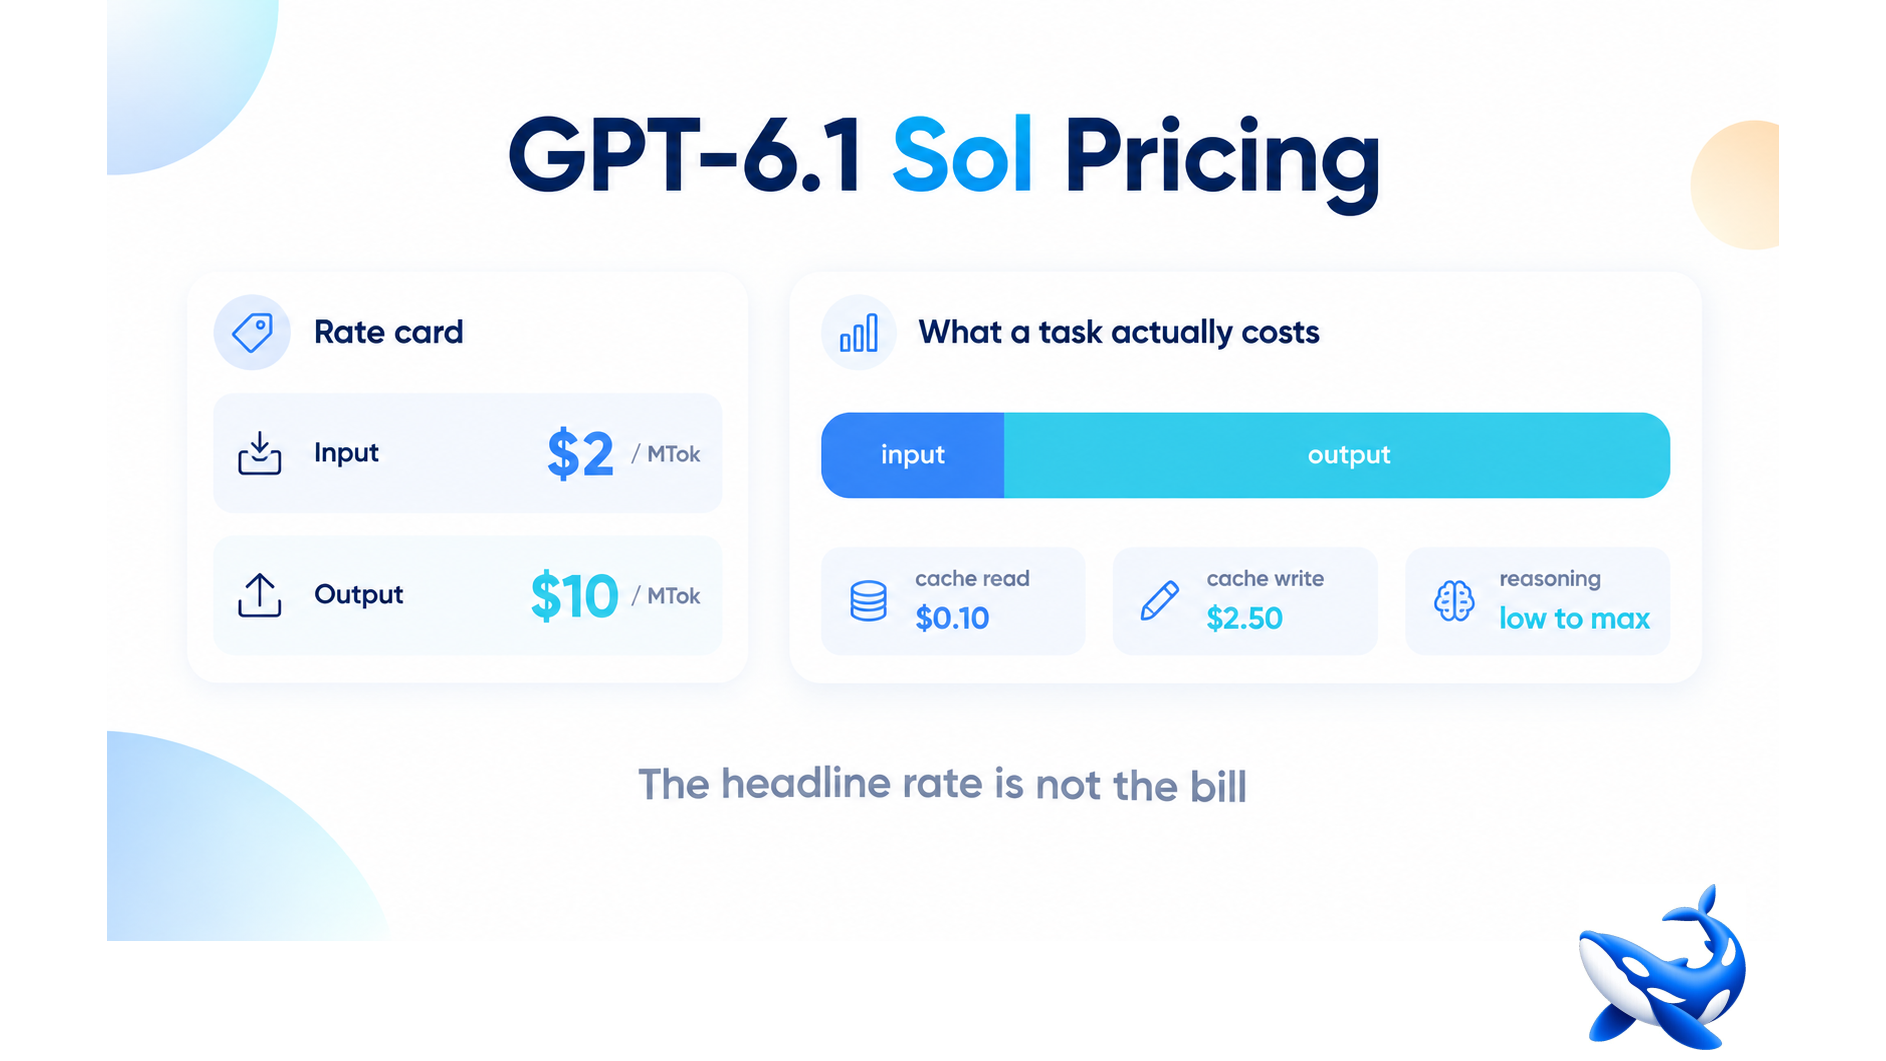
The published GPT-6.1 Sol pricing is simple enough to memorise: $2 per million input tokens, $10 per million output, $0.10 per million for cached reads, $2.50 per million for cache writes. Those are OpenAI's own list rates, unreproduced, and the GPT-6.1 Sol endpoint here is metered at exactly that — no markup, no platform fee, no minimum. What is not simple is what those numbers do to a monthly bill, because the ratio between them is not the ratio you will experience.
Here is the arithmetic that matters, and it is the one nobody puts on a pricing page.
The bar, not the two numbers
A rate card gives you a price per token in each direction. A bill is a quantity in each direction multiplied by that price. So the only question that decides your cost is: how many of the tokens you pay for are input, and how many are output?
For a chat-shaped workload, the answer is not close. A long system prompt, a retrieved document set, a tool schema, a conversation history — all of that is input, re-sent on every turn. The answer is a few hundred tokens. A ratio of thirty-to-one input-heavy is ordinary for a retrieval-augmented setup, and ratios above a hundred-to-one are common once you are feeding whole files.
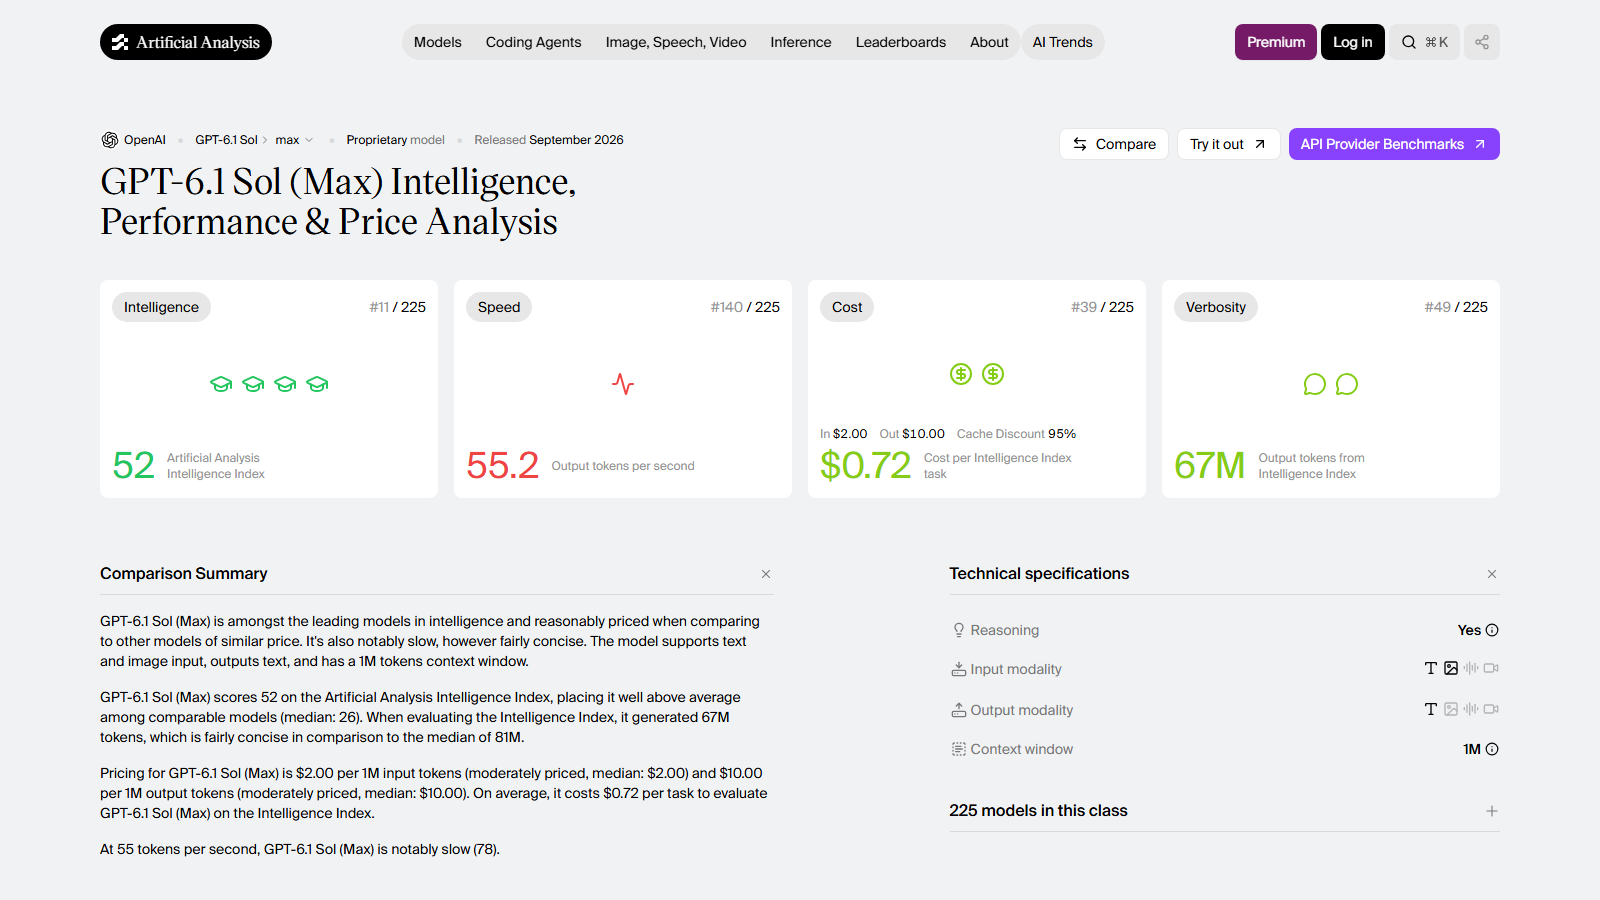
Run that through the card. At $2 in and $10 out, a hundred input tokens cost $0.0002 and one output token costs $0.00001. Your input is twenty times your output on that turn, even though the output rate is five times the input rate. On the independent task set that Artificial Analysis publishes, GPT-6.1 Sol's per-task cost breaks down with input at $0.343 against a total of $0.7242 — so the *cheaper-per-token* direction is slightly under half the bill, and that is on a benchmark harness that is far more output-heavy than production retrieval usually is.
The consequence is blunt: your input rate is the number that decides your invoice, and it is the number most people skim past.
Why the cache line is the real pricing news
Which is why the cache-read price deserves its own section rather than a footnote.
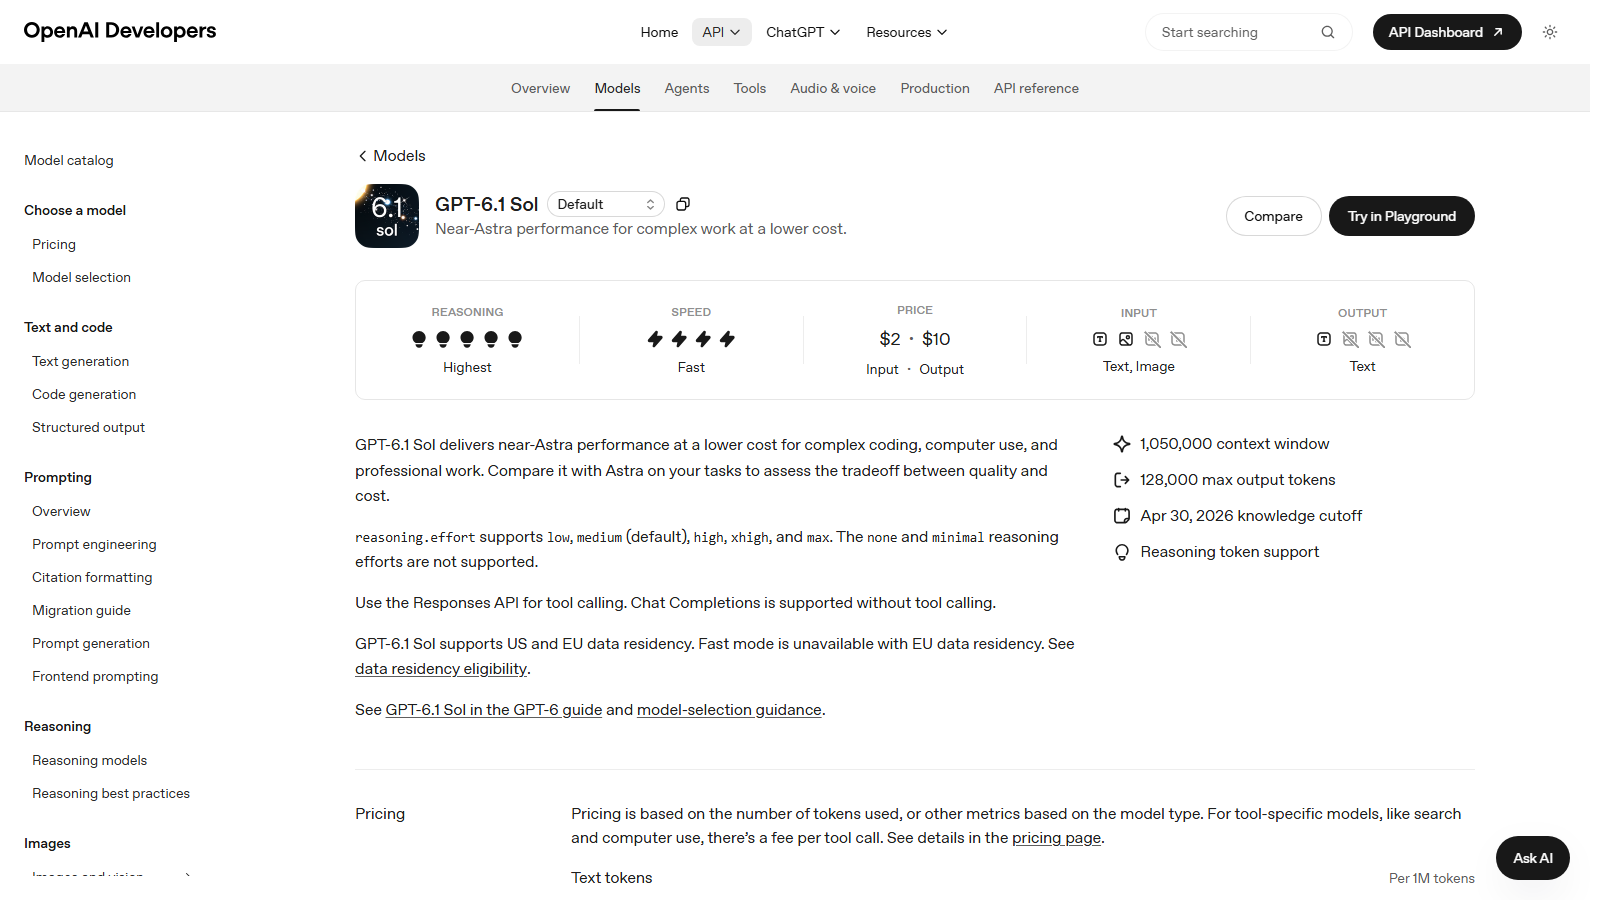
Cached input reads cost $0.10 per million tokens on GPT-6.1 Sol — one twentieth of the standard input rate, and, more to the point, half what GPT-6 Sol charged for the same thing ($0.20). If your workload has a stable prefix — a system prompt, a fixed instruction block, a schema — then the portion of your input that can be cached is being billed at a twentieth of the rate you were probably estimating against.
The multiplier this creates is not marginal. A workload that is 90% cacheable input and 10% fresh input does not cost 90% of what a naive estimate says; it costs roughly a fifth of it, because the cacheable portion drops by a factor of twenty and only the fresh tenth stays at full rate.
Cache writes are the counterweight and are priced at $2.50 per million — above the standard input rate, which is the mechanism working as intended: you pay a premium once to write the prefix, and then read it cheaply for as long as it lives. Whether that trade pays off is entirely a question of reuse count. A prefix read twice does not repay its write premium. A prefix read fifty times repays it many times over. That is the calculation to run, and it is a one-line division — *write price ÷ (standard input − cache read) = break-even reuse count* — which for GPT-6.1 Sol comes out at about two.
The tier above 272K
There is one more line, and it is ours rather than the vendor's.
On our own rate card, requests above 272,000 input tokens are billed at a higher tier for GPT-6.1 Sol — $4 input and $15 output rather than $2 and $10. That tiering is OrcaRouter's, not a line from OpenAI's published card: a long-context request costs more upstream, and we surface the step rather than bury it in an overage notice.
The practical rule is arithmetic: 272,000 tokens is about a quarter of the advertised context window. If your workload sends the full million-token window on every call, you are not on the $2 rate for that call, and no amount of caching changes which tier the request lands in.
What a workload actually costs, worked through
Put the pieces together on a concrete shape. Take an agent that runs 2,000 calls a day, each sending a 30,000-token cached prefix, 5,000 tokens of fresh retrieval, and generating 1,500 tokens of output. That is 60 million cached input tokens, 10 million fresh input tokens, and 3 million output tokens per day.
|
component |
tokens/day |
rate |
daily cost |
|
cached input |
60,000,000 |
$0.10 / MTok |
$6.00 |
|
fresh input |
10,000,000 |
$2.00 / MTok |
$20.00 |
|
output |
3,000,000 |
$10.00 / MTok |
$30.00 |
|
total |
$56.00 |
Three observations fall out of that table, and all three are counter-intuitive against the rate card.
The cached prefix — 60 million tokens, by far the largest quantity in the workload — costs less than the output, which is a twentieth of its size. Caching is not a discount; on input-heavy work it is the difference between a viable unit economics model and an unviable one.
The output column is the largest single line at $30, despite output being 4% of the token volume. The $10 rate earns its reputation.
And the fresh input column at $20 is the one to attack next, because it is the only line where the model's behaviour rather than your architecture is setting the price. Trimming retrieval that does not earn its place is worth more here than any prompt-length micro-optimisation.
The comparison that puts it in proportion
GPT-6 Astra costs five times as much per token — $10 in, $50 out — on a spec sheet that is the same on paper: identical 1.05M context window, identical 128K output ceiling, identical reasoning ladder from low to max. Both are OpenAI's own published numbers.
The independent per-task figure lands where you would expect from the rate ratio: about $3.26 a task for Astra against $0.72 for Sol, roughly 4.5×. So on that comparison, the five-times rate card buys you something close to a 4.5× bill. Whether the capability difference justifies it is a separate question, and the honest answer from the benchmark record is that Astra's published evidence base is roughly three times the size of Sol's — 45 rows of 68 against 14 of 31, both read 2026-10-07. You are partly paying for a better-measured model, not only a better one.
The takeaway
GPT-6.1 Sol's rate card is a good one, and it is a good one for a specific reason that the card does not advertise: the input direction is cheap, the cached input direction is twenty times cheaper, and its cache read got halved against the model it replaces. For retrieval-heavy and agent-shaped work — which is most of what people actually build — that combination is where the money is saved.
Budget against the shape of your traffic, not against the two headline rates. Estimate your input-to-output ratio, estimate what fraction of your input has a stable prefix, and remember that a request past 272,000 tokens leaves the base tier. Do those three things and the invoice stops surprising you.
OrcaRouter meters GPT-6.1 Sol at list rate on the same key as the rest of the OpenAI line, so a cost estimate you build from this article is a cost estimate you can verify against an actual invoice without a procurement cycle.
Sourcing note: all four rates ($2 / $10 input and output, $0.10 cache read, $2.50 cache write) are OpenAI's published list prices for GPT-6.1 Sol and have not been independently reproduced; the comparison to GPT-6 Sol's $0.20 cache read is an independent record rather than a vendor claim. The 272K tier is OrcaRouter's own rate card, not the vendor's. Per-task cost figures ($0.7242 for Sol, ~$3.26 for Astra) and the reasoning-effort context behind them are from Artificial Analysis' live model pages, read 2026-10-07, where both models are measured at the Max effort setting. Benchmark coverage counts (14 of 31 rows, 45 of 68) are from benchlm.ai, read 2026-10-07. All checked 2026-10-07.