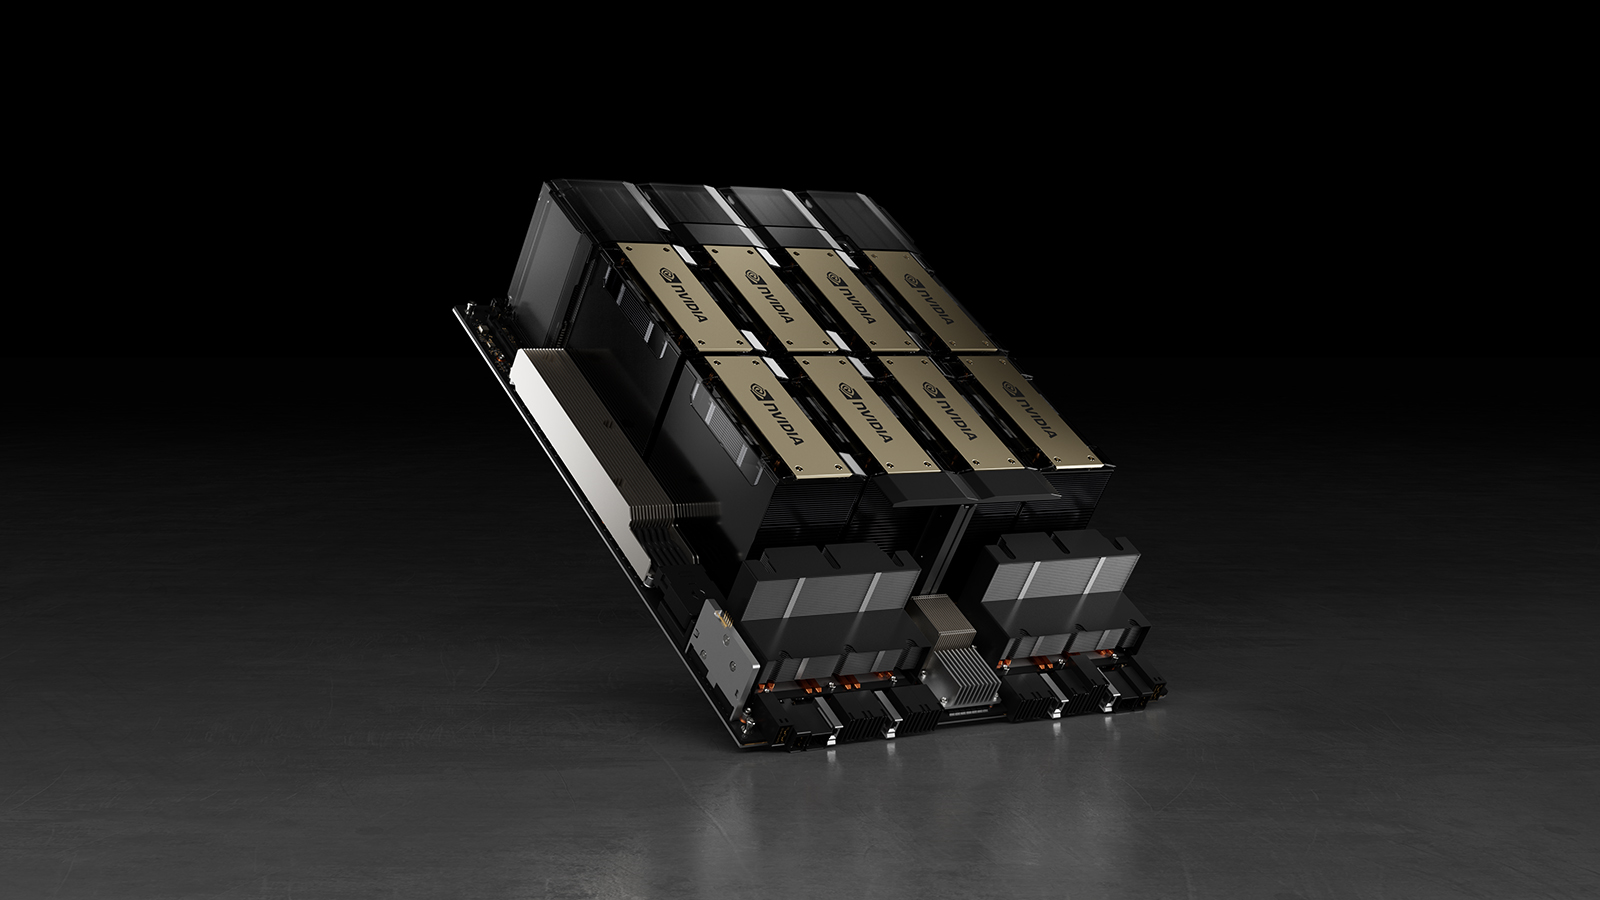
Meta recently released a study detailing its Llama 3 405B model training run on a cluster containing 16,384 Nvidia H100 80GB GPUs. The training run took place over 54 days and the cluster encountered 419 unexpected component failures during that time, averaging one failure every three hours. In half of the failure cases, GPUs or their onboard HBM3 memory were to blame.
As the old supercomputing adage goes, the only certainty with large-scale systems is failure. Supercomputers are extremely complex devices that use tens of thousands of processors, hundreds of thousands of other chips, and hundreds of miles of cables. In a sophisticated supercomputer, it's normal for something to break down every few hours, and the main trick for developers is to ensure that the system remains operational regardless of such local breakdowns.