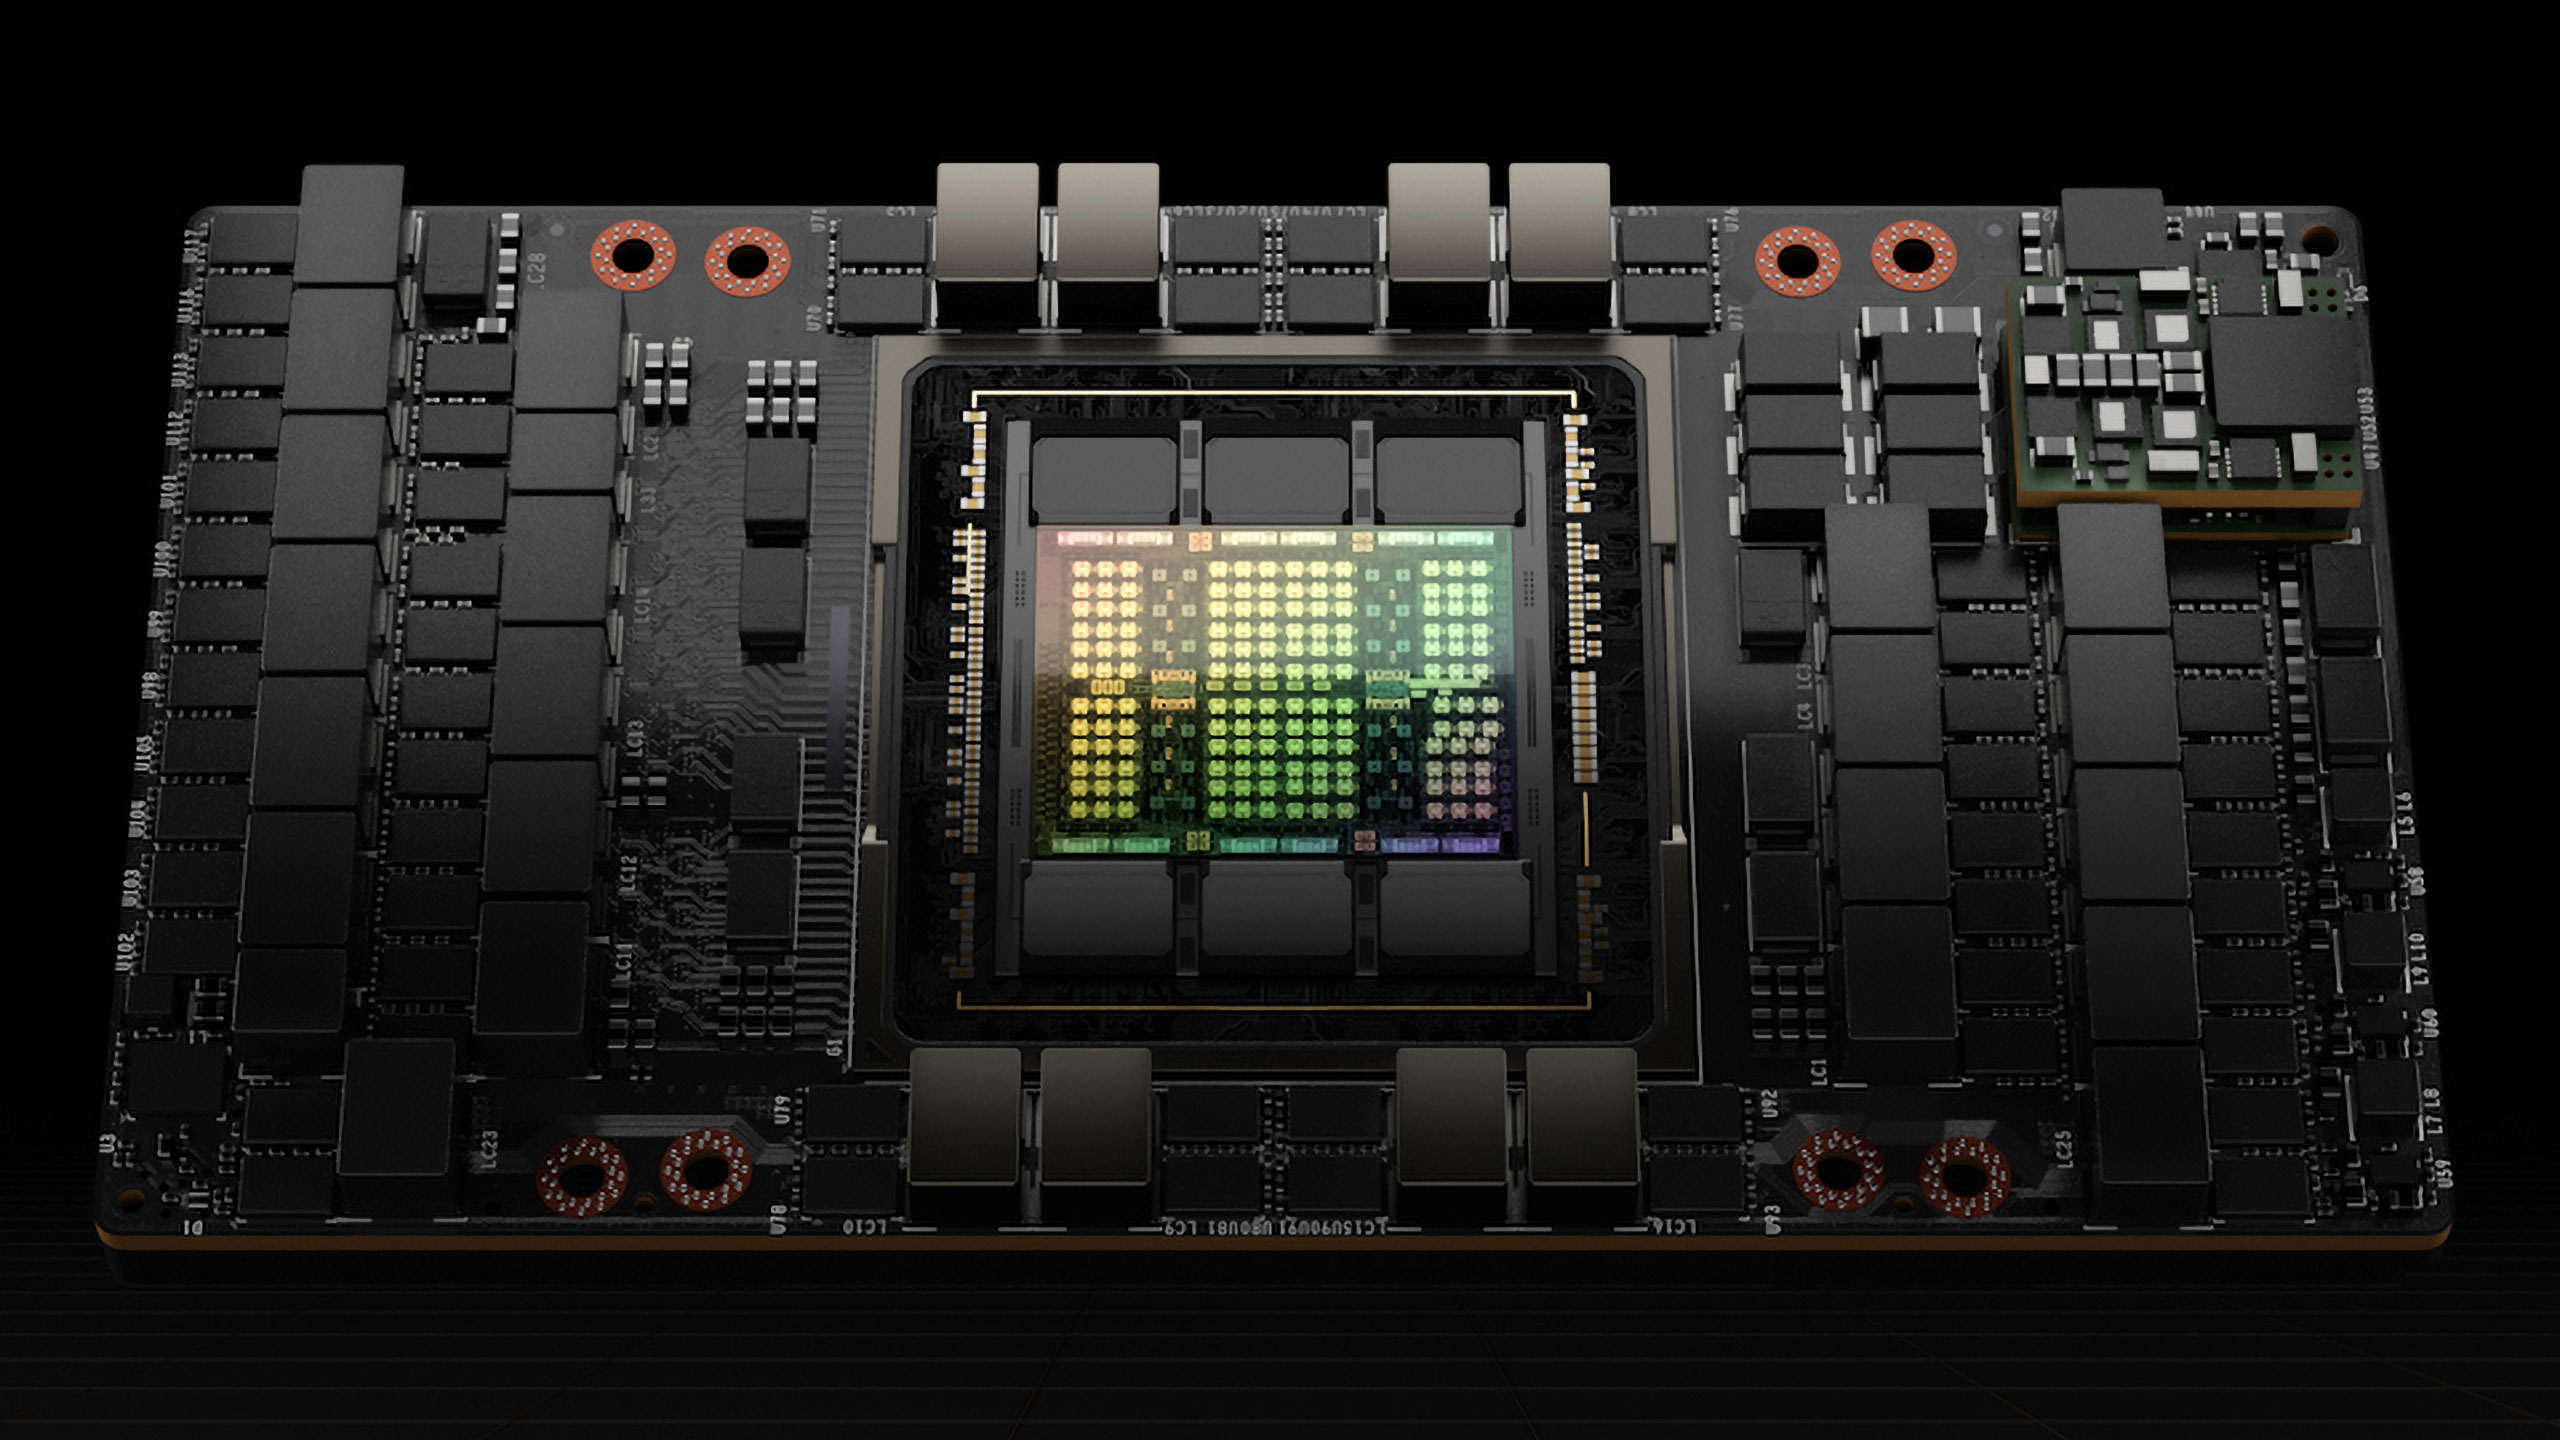
DeepSeek made quite a splash in the AI industry by training its Mixture-of-Experts (MoE) language model with 671 billion parameters using a cluster featuring 2,048 Nvidia H800 GPUs in about two months, showing 10X higher efficiency than AI industry leaders like Meta. The breakthrough was achieved by implementing tons of fine-grained optimizations and usage of Nvidia's assembly-like PTX (Parallel Thread Execution) programming instead of Nvidia's CUDA for some functions, according to an analysis from Mirae Asset Securities Korea cited by @Jukanlosreve.
Today: OpenAI boss Sam Altman calls DeepSeek 'impressive.' In 2023 he called competing nearly impossible.
Jan. 28, 2025: Investors panic: Nvidia stock loses $589B in value.
Dec. 27, 2024: DeepSeek is unveiled to the world.