
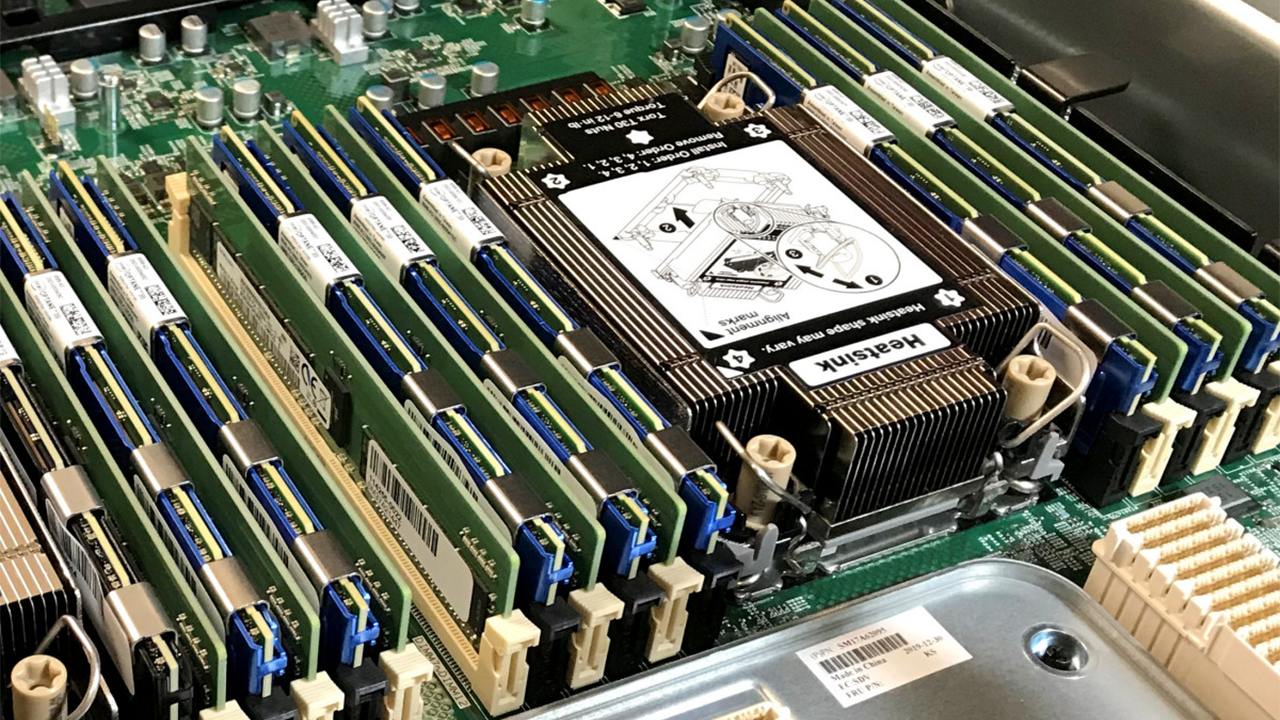
A Redditor has caused a stir by coaxing a workstation build using Optane PMem DIMMs as RAM to run a 1-trillion-parameter LLM. APFrisco explains in a mini tutorial/guide on the Local LLaMA subreddit how they bought some used Intel Optane Persistent Memory, acquired relatively cheaply second-hand, to “run a 1 trillion parameter model (in this case Kimi K2.5) locally at ~4 tokens/second” on their Xeon workstation.
Computer build using Intel Optane Persistent Memory - Can run 1 trillion parameter model at over 4 tokens/sec from r/LocalLLaMA




