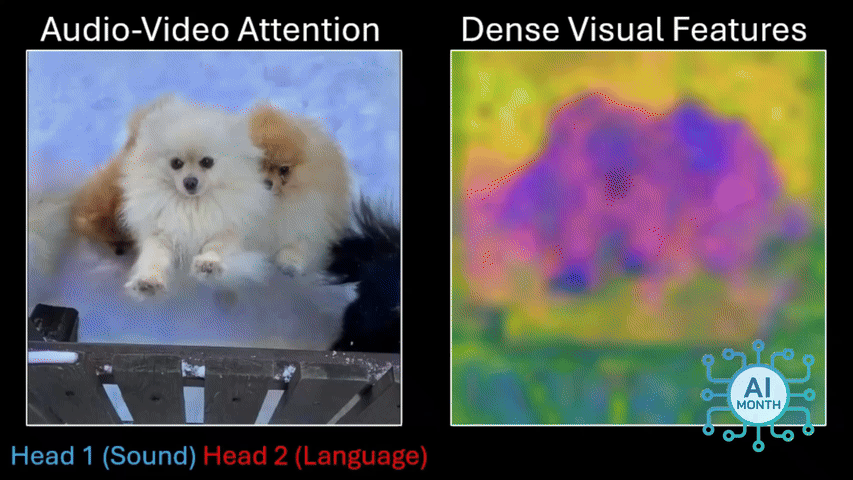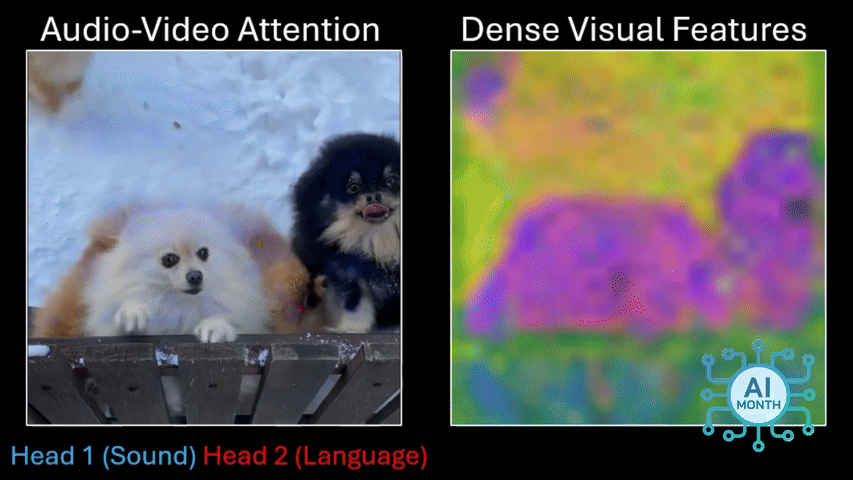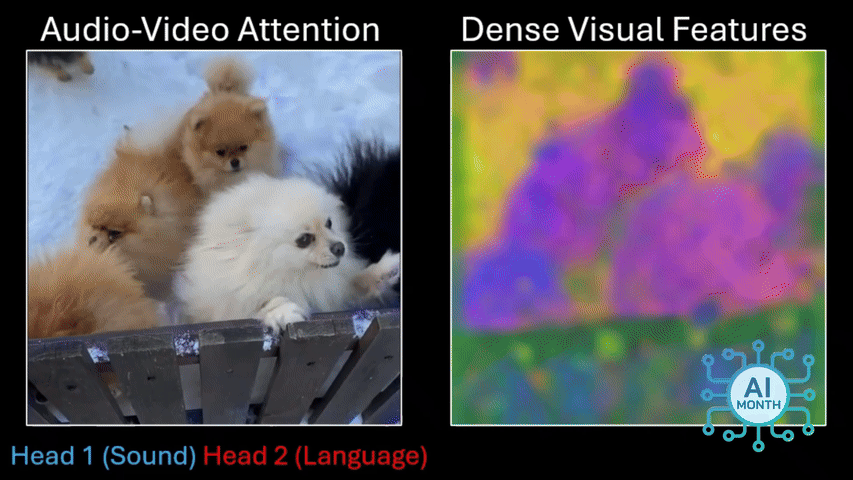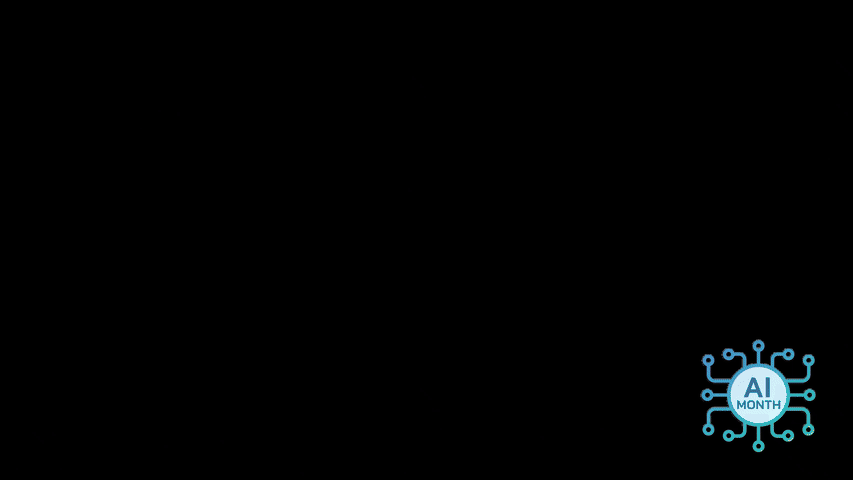
The AI model DenseAV is learning the meaning of words and the location of sounds without human input or text simply by watching videos, researchers said.
In a paper, researchers from MIT, Microsoft, Oxford, and Google explained that DenseAV manages to do so using only self-supervision from video.