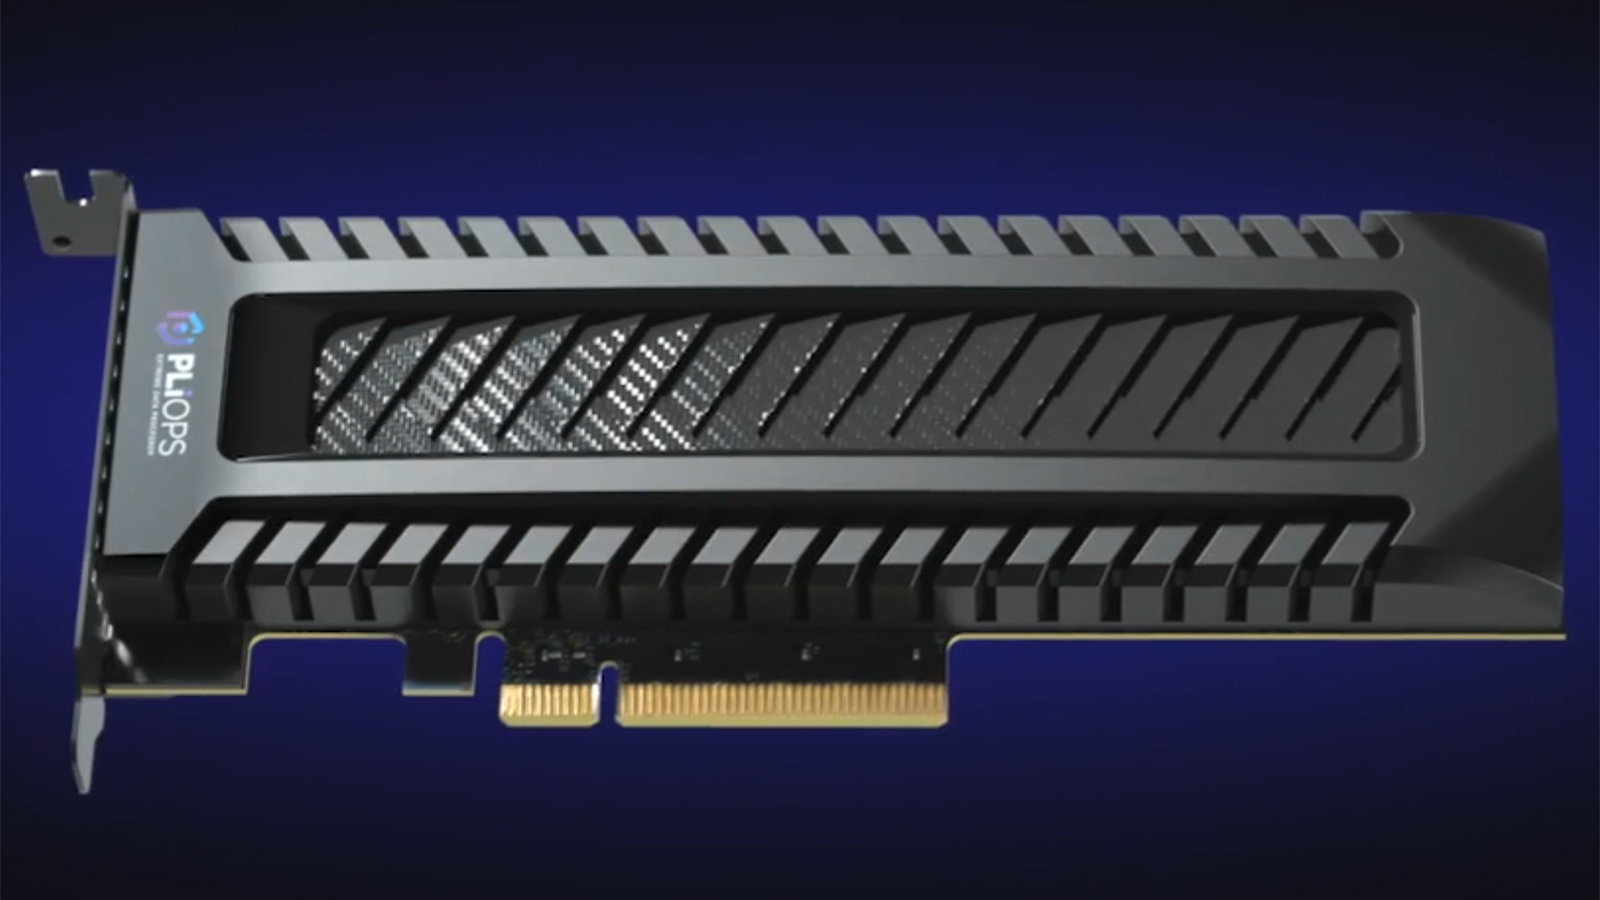
As language models grow in complexity and their context windows expand, GPU-attached high bandwidth memory (HBM) becomes a bottleneck, forcing systems to repeatedly recalculate data that no longer fits in onboard HBM. Pliops has addressed this challenge with its XDP LightningAI device and FusIOnX software, which store precomputed context on fast SSDs and retrieve it instantly when needed, reports Blocks and Files. The company says that its solution enables 'nearly' HBM speeds and can accelerate certain inference workflows by up to eight times.
During inference, language models generate and reference key-value data to manage context and maintain coherence across long sequences. Normally, this information is stored in the GPU's onboard memory, but when the active context becomes too large, older entries are discarded, forcing the system to redo calculations if those entries are needed again, which increases latency and GPU load. To eliminate these redundant operations, Pliops has introduced a new memory tier that is enabled by its XDP LightningAI machine, a PCIe device that manages the movement of key-value data between GPUs and tens of high-performance SSDs.