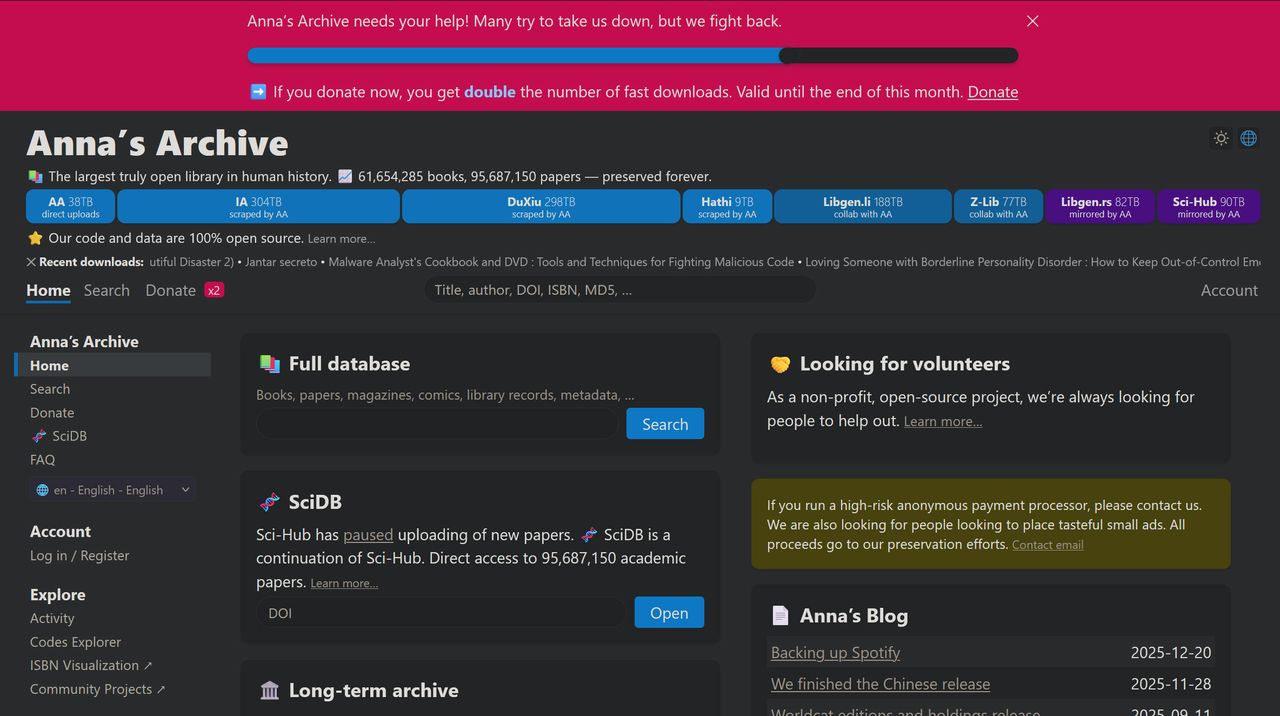
Nvidia is pushing back against claims that it trained AI models on pirated books, telling a federal court in California that its alleged contact with the library ‘Anna’s Archive’ doesn’t amount to proof of copyright infringement.
In a motion to dismiss filed January 29, the company argues that the authors behind Nazemian v Nvidia have failed to plausibly show that their specific works were downloaded or used in training, despite expanding their complaint to include new theories and datasets.