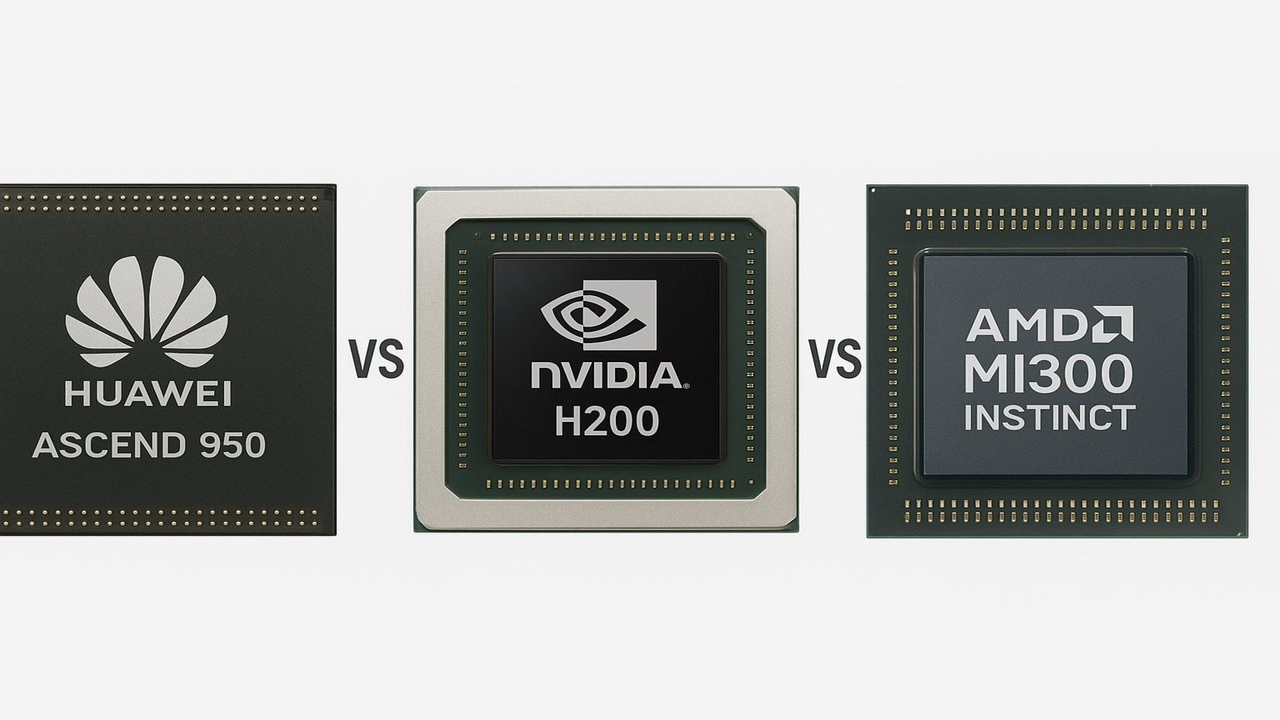
- Huawei Ascend 950DT FP8 formats target efficient inference without accuracy loss
- Nvidia H200 leans on a mature software ecosystem and Hopper GPU strengths
- AMD Instinct MI300’s FP64 parity appeals to serious scientific computation workloads
In recent years, the demand for AI training and inference computing has pushed chip makers to innovate aggressively - efficiency in memory bandwidth, data formats, interconnects, and total compute output are now as critical as raw FLOPS.