One of Nvidia's advantages in the data center space is that it not only offers leading-edge GPUs for AI and HPC computing but can also effectively scale the number of its processors across a data center using its own hardware and software. How could you defeat Nvidia if your GPUs are slower and your software stack is not as pervasive as Nvidia's CUDA? Well, expand your own scale-out capabilities. This is exactly what Chinese GPU maker Moores Threads has done, based on a Science China Morning Post report.
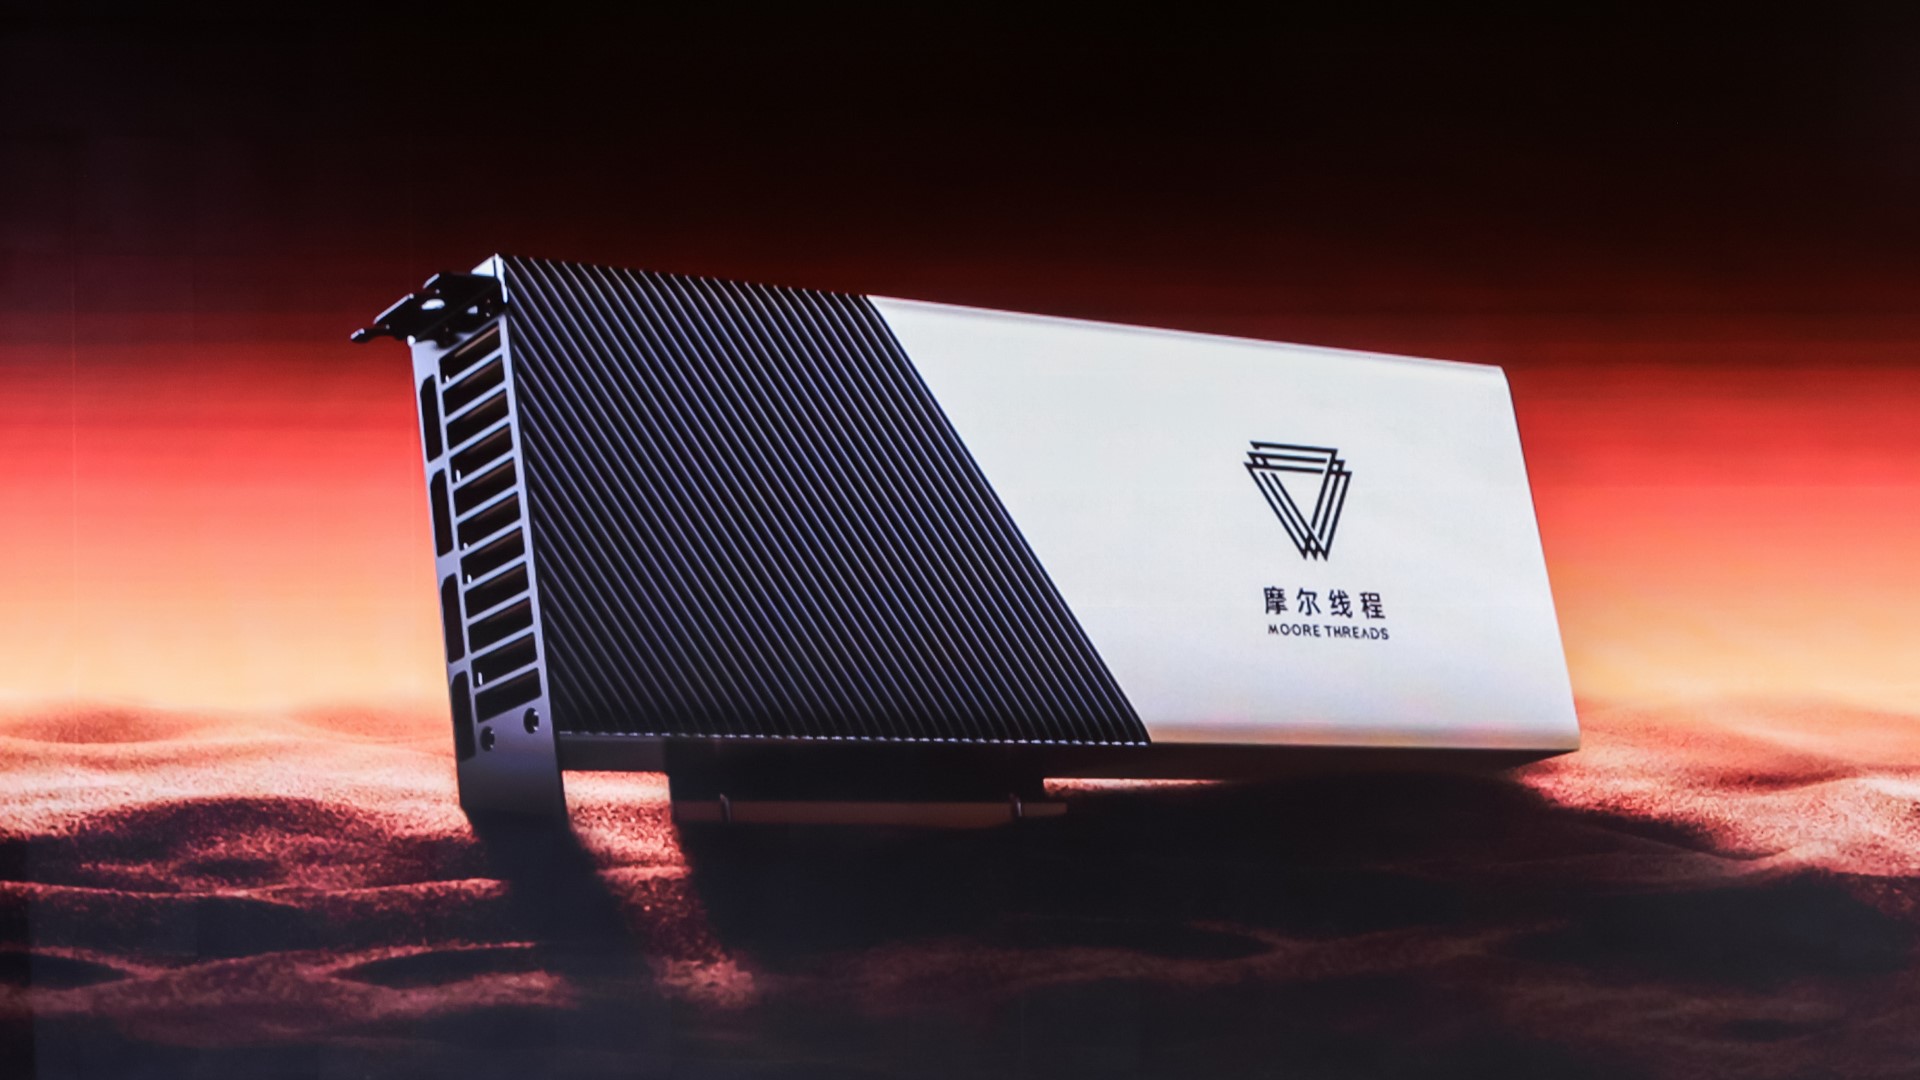
Moore Threads has upgraded its KUAE data center server for AI, enabling connecting up to 10,000 GPUs in a single cluster. The KUAE data center servers integrate eight MTT S4000 GPUs interconnected using the proprietary MTLink technology designed specifically for training and running large language models (LLMs). These GPUs are based on the MUSA architecture and feature 128 tensor cores and 48 GB GDDR6 memory with 768 GB/s of bandwidth. A 10,000-GPU cluster wields 1,280,000 tensor cores, but the actual performance is unknown as performance scaling depends on numerous factors.