A San Francisco start-up has spent the past six months running one of the more unusual data projects in AI. Conduit says it has collected roughly 10,000 hours of non-invasive neural data from “thousands of unique individuals” in a basement studio, forming what it believes is the largest neuro-language dataset assembled to date. The company is using the recordings to train thought-to-text AI models that attempt to decode semantic content from brain activity in the seconds before a participant speaks or types.
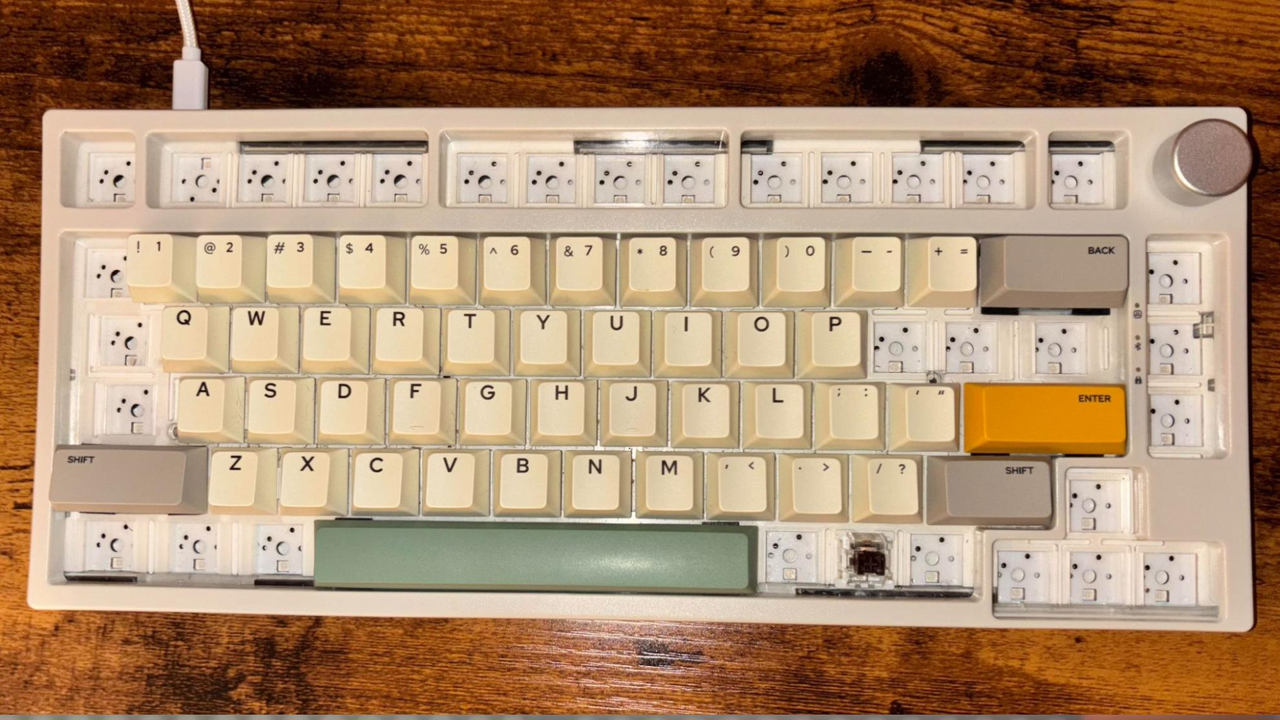
Participants sit for two-hour sessions in small booths and converse freely with an LLM through speech or typing on “simplified” keyboards. Early sessions relied on rigid tasks, but Conduit shifted to personalized back-and-forth conversation after noticing that engagement strongly influenced data quality. The goal is to maximize the amount of natural language produced during each recording while maintaining tight time alignment between text, audio, and neural signals.